Before connecting anything, listen to the person doing the work
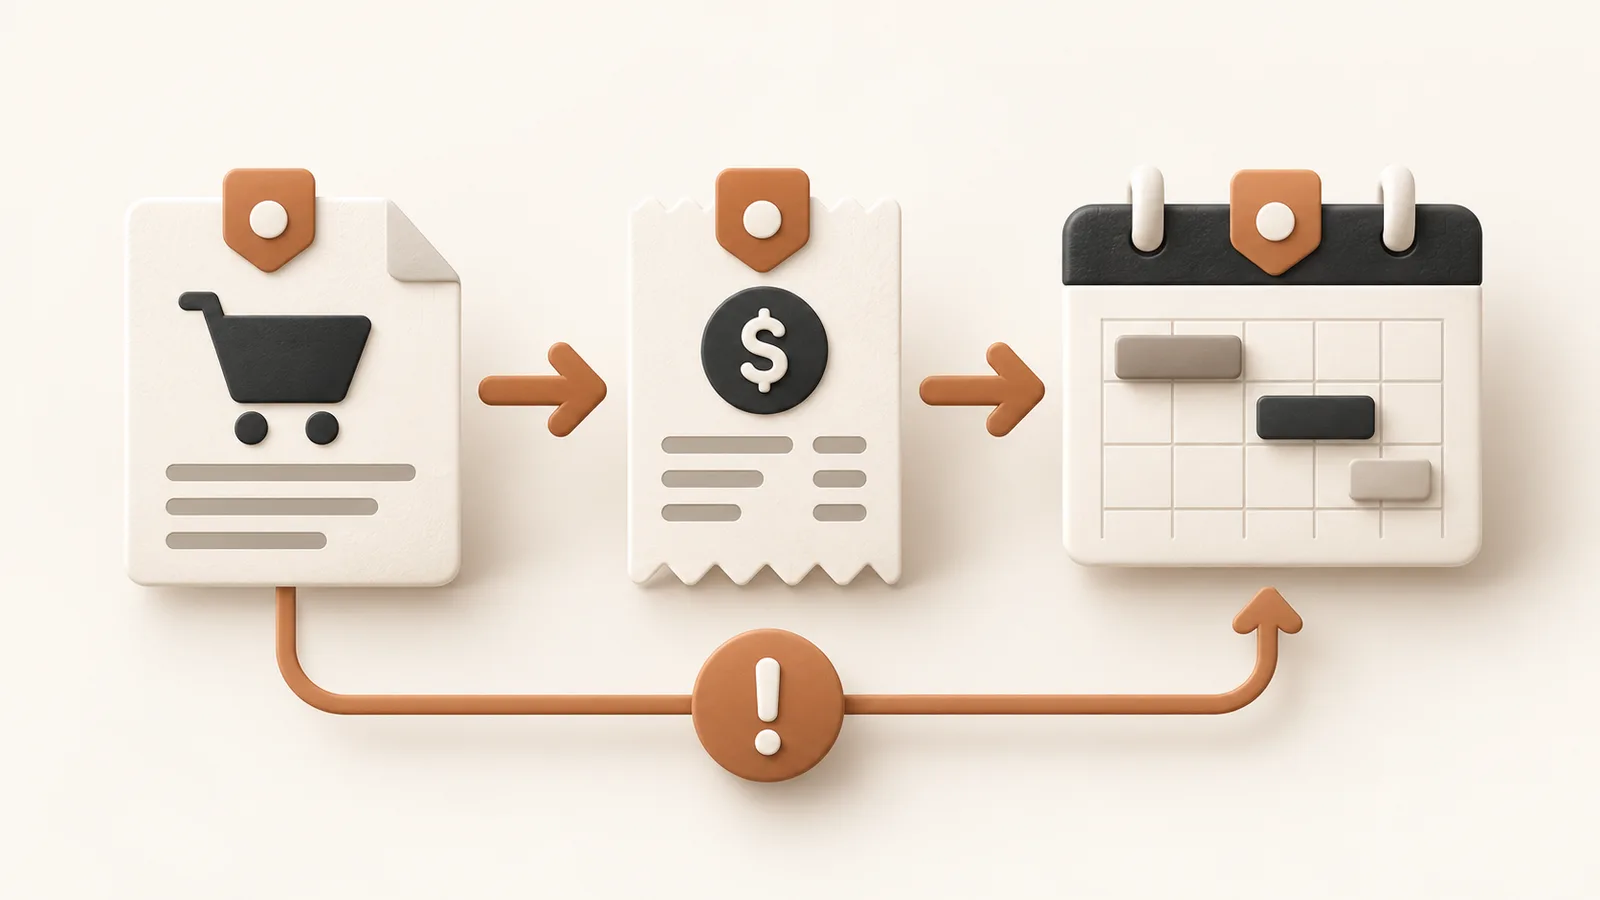
Imagine someone who receives orders on a website, copies them into an invoicing tool and then organizes deliveries in a calendar. They know the process by heart. They also know what to do when a customer changes their mind, even if that step has never been written down.
Before automating anything, it’s worth sitting down with them. When is an order ready to be invoiced? What happens if its date changes or it gets canceled? Listening to those answers helps me understand the work I want to make easier. Choosing an API or an automation tool can wait a little.
I’d start with a small part: once an order is approved, send the invoicing request and keep its reference. Then I can follow one complete case, review what happens with you and make adjustments before connecting the rest.
Give each piece of information a clear home
In this example, the website can hold the order, the invoicing tool can manage the invoice, and the calendar can receive what’s needed to prepare the delivery. Another business may need to divide those responsibilities differently. What matters is that the team knows where to look up and correct each detail.
I’d give the order a reference that stays the same across all three tools. Looking it up by the customer’s name can be confusing: two people can have the same name. A shared reference makes it possible to say “this is their invoice and this is their delivery” without opening several tabs and guessing which one belongs to them.
When something fails, someone needs to know what to do
A request can go unanswered even though the operation completed. Repeating it without checking could create another record. Amazon explains how a request identifier can recognize retries of the same operation. This property is called idempotency: repeating the request should not repeat its effect.Amazon Builders’ Library: safe retries and idempotency ↗
I’ll come back to the invoice example. Trying to create it again because no response arrived is different from asking for another invoice. Before adding automatic retries, I’d check whether the receiving tool can recognize that difference. If it can’t, there needs to be a way to check what happened or review the case.
Think about the person waiting at the other end, too. If invoicing stops responding, they need to see which orders are still pending and how to resume them. A clear message and a useful next step do more for them than an error hidden in a file that only the technical team can read.
Be able to explain where a piece of data came from
At Healthier, I built a validator to detect duplicates and preserve references to source files and extracted data. That connection makes it possible to return to the source when a result needs reviewing. It’s a part of that work I want to carry into other integrations: being able to explain where the information came from.
For the orders in this example, I’d keep the source reference, the requested action, the response and the status. That context gives me somewhere to start an investigation. I’d also be careful about what gets stored: I want to understand the process while respecting the privacy of the people whose information it contains.
Test it with the people who will use it
I’d take a test order and follow it through to delivery. Then I’d repeat an invoicing attempt, change a detail and simulate an interruption. Together with the team, I’d check whether it’s clear what happened and whether there’s a way to continue. That moment can reveal details the diagram didn’t show.
Before adding another connection, I’d make clear who maintains it and where to ask for help. I want an integration to take work off the team’s shoulders, and when something stops, I don’t want anyone to feel lost in front of a screen. That part of development deserves care, too.